The training of Large Language Models (LLM) uses large data sets to learn about conventions of which words are combined with each other and which ones are less frequently employed in conjunction. Therefore, it does not really come as a surprise that training which uses standardised languages of American English might not be as valid for applications that receive input from minority languages or dialects. The study forthcoming in the field of Computer science and Language by Hofmann et al. (Link) provides evidence of the systematic bias against African American dialects in these models. Dialect prejudice remains a major concern in AI, just like in the day-to-day experiences of many people speaking a dialect. The study highlights that dialect speakers are more likely to be assigned less prestigious jobs if AI is used to sort applicants. Similarly, criminal sentences will harsher for speakers of African American. Even the more frequent attribution of death sentences for dialect speakers was evidenced.
If we translate this evidence to wide-spread applications of AI in the workplace, we realise that there are severe issues to resolve. The European Trade Union Congress (ETUC) has flagged the issue for some time (Link) and made recommendations of how to address these shortcomings. Human control and co-determination by employees are crucial in these applications to the world of work and employment. The need to justify decision-making concerning hiring and firing limit discrimination in the work place. This needs to be preserved in the 21st century collaborating with AI. The language barriers like dialects or multiple official languages in a country ask for a reconsideration of AI to avoid discrimination. Legal systems have to clarify the responsibilities of AI applications before too much harm has been caused.
There are huge potentials of AI as well in the preservation of dialects or interacting in a dialect. The cultural diversity may be preserved more easily, but discriminatory practices have to be eliminated from the basis of these models otherwise they become a severe legal risk for people, companies or public services who apply these large language models without careful scrutiny.
(Image AI BING Designer: 3 robots are in an office. 2 wear suits. 1 wears folklore dress. All speak to each other in a meeting. Cartoon-like style in futuristic setting) 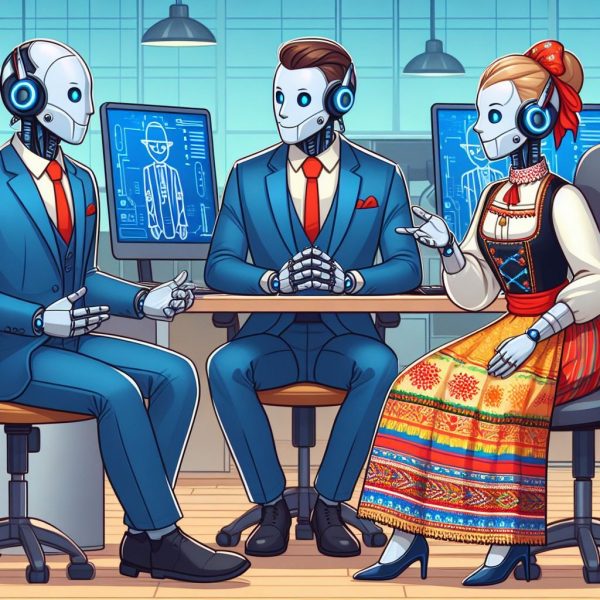
Energy Storage
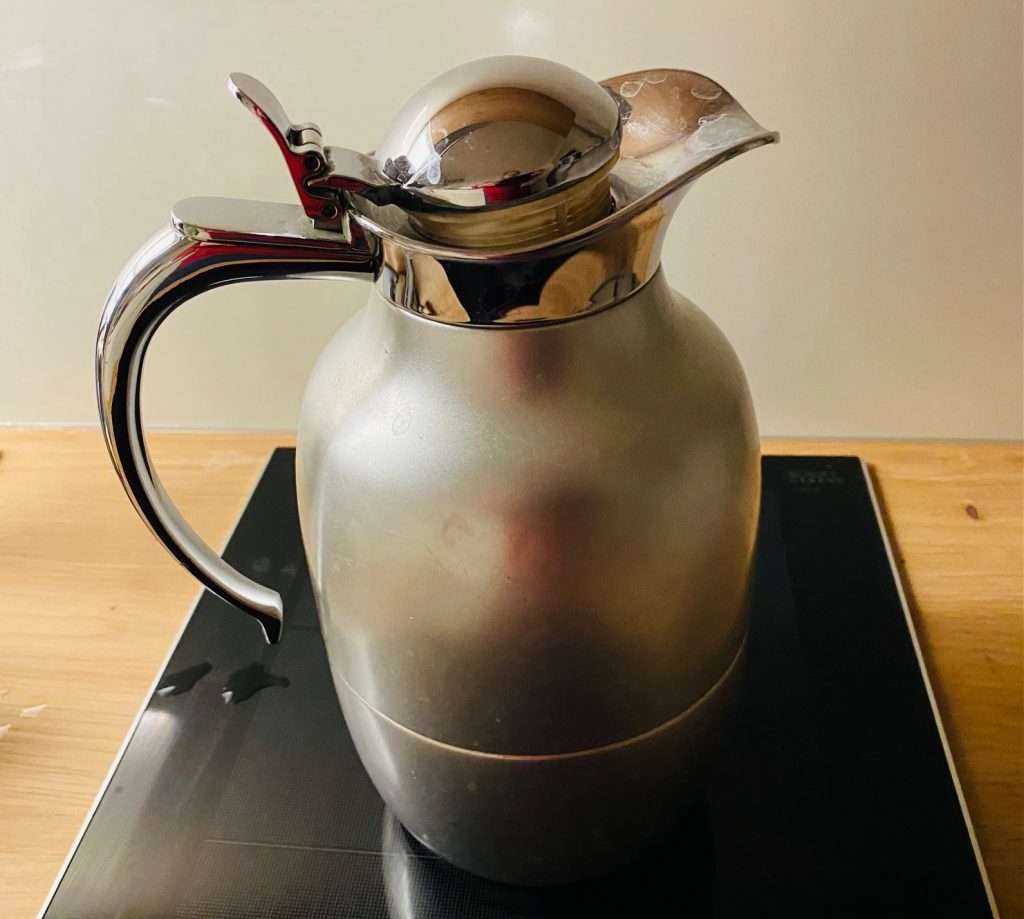
On a sunny and windy day, even in winter or spring, renewable energy is abundant. If demand is stable prices will drop. Prices will rise again as demand for energy picks up. Hence, this is an obvious case for trading opportunities. All you need is … energy storage. All so-called prosumers, short for producers and simultaneously consumers have a lot to gain if they are able to store energy when it’s abundant and cheap. Sell it when it is expensive or use it yourself if needed. Just keep an eye on the costs of energy storage. A stylish insulated carafe is a well known example of storing hot water for astonishingly long time. Insulation is key to store transformed electric energy here. Other options use kinetic energy like pumping water to a higher level and then generate electricity again when the water returns to the lower level. Of course, batteries are a simple way for energy storage as well. Costs seem to come down rapidly and less environmentally hazardous materials leave the laboratory almost every month. It is about time to consider this seriously. More and more cities have understood that energy storage can generate cash for them (Example Feuchtwangen) and appears to be a worthwhile investment for a local power generating community. For the time being my favorite energy storage is the insulated carafe. It is often the beginning of energizing conversations.
AI Collusion
In most applications of AI there is one system of AI, for example a specialized service, that performs in isolation from other services. More powerful systems, however, allow for the combination of AI services. This may be useful in case of integrating services focusing on specialized sensors to gain a more complete impression of the performance of a system. As soon as two and more AI systems become integrated the risk of unwanted or illegal collusion may occur.
Collusion is defined in the realm of economic theory as the secret, undocumented, often illegal, restriction of competition originating from at least two otherwise rival competitors. In the realm of AI collusion has been defined by Motwani et al. (2024) as “teams of communicating generative AI agents solve joint tasks”. The cooperation of agents as well as the sharing of of previously exclusive information increase the risks of violation of rights of privacy or security. The AI related risks consist also in the dilution of responsibility. It becomes more difficult to identify the origin of fraudulent use of data like personal information or contacts. Just imagine using Alexa and Siri talking to each other to develop another integrated service as a simplified example.
The use of steganography techniques, i.e. the secret embedding of code into an AI system or image distribution, can protect authorship as well as open doors for fraudulent applications. The collusion of AI systems will blur legal borders and create multiple new issues to resolve in the construction and implementation of AI agents. New issues of trust in technologies will arise if no common standards and regulations will be defined. We seem to be just at the entry of the new brave world or 1984 in 2024.
(Image: KI MS-Copilot: Three smartphones in form of different robots stand upright on a desk in a circle. Each displays text on a computer image.)
AI input
AI is crucially dependent on the input it is built on. This has been already the foundation principle of the powerful search engines like Google that have become to dominate the commercial part of the internet. The crawling of pages on the world wide web and classifying/ranking them with a number of criteria has been the successful business model. The content production was and is done by billions of people across the globe. Open access facilitates the amount of data available.
The business case for AI is not much different. At the 30th anniversary of the “Robots Exclusion Standard” we have to build on these original ideas to rethink our input strategies for AI as well. If there are parts of our input we do not AI to use in its algorithms we have to put up red flags in form of unlisting parts of the information we allow for public access. This is standard routine we might believe, but everything on the cloud might have made it much easier for owners of the cloud space to “crawl” your information, pictures or media files. Some owners of big data collections have decided to sell the access and use to their treasures. AI can then learn from these data.
Restrictions become also clear. More up-to-date information might not be available for AI-treatment. AI might lack the most recent information, if it a kind of breaking news. The strength of AI lies in the size of data input it can handle and treat or recombine. The deficiency of AI is not to know whether the information it uses (is in the data base) is valid or trustworthy. Wrong or outdated input due to a legal change or just-in-time change will be beyond its scope. Therefore, the algorithms have a latent risk involved, i.e. a bias towards the status quo. But the learning algorithms can deal with this and come up with a continued learning or improvement of routines. In such a process it is crucial to have ample feedback on the valid or invalid outcome of the algorithm. Controlling and evaluating outcomes becomes the complementary task for humans as well as AI. Checks and balances like in democratic political systems become more and more important.